Cut your inference costs in half.
The only LLM gateway that adapts to your traffic. Built for companies scaling AI.
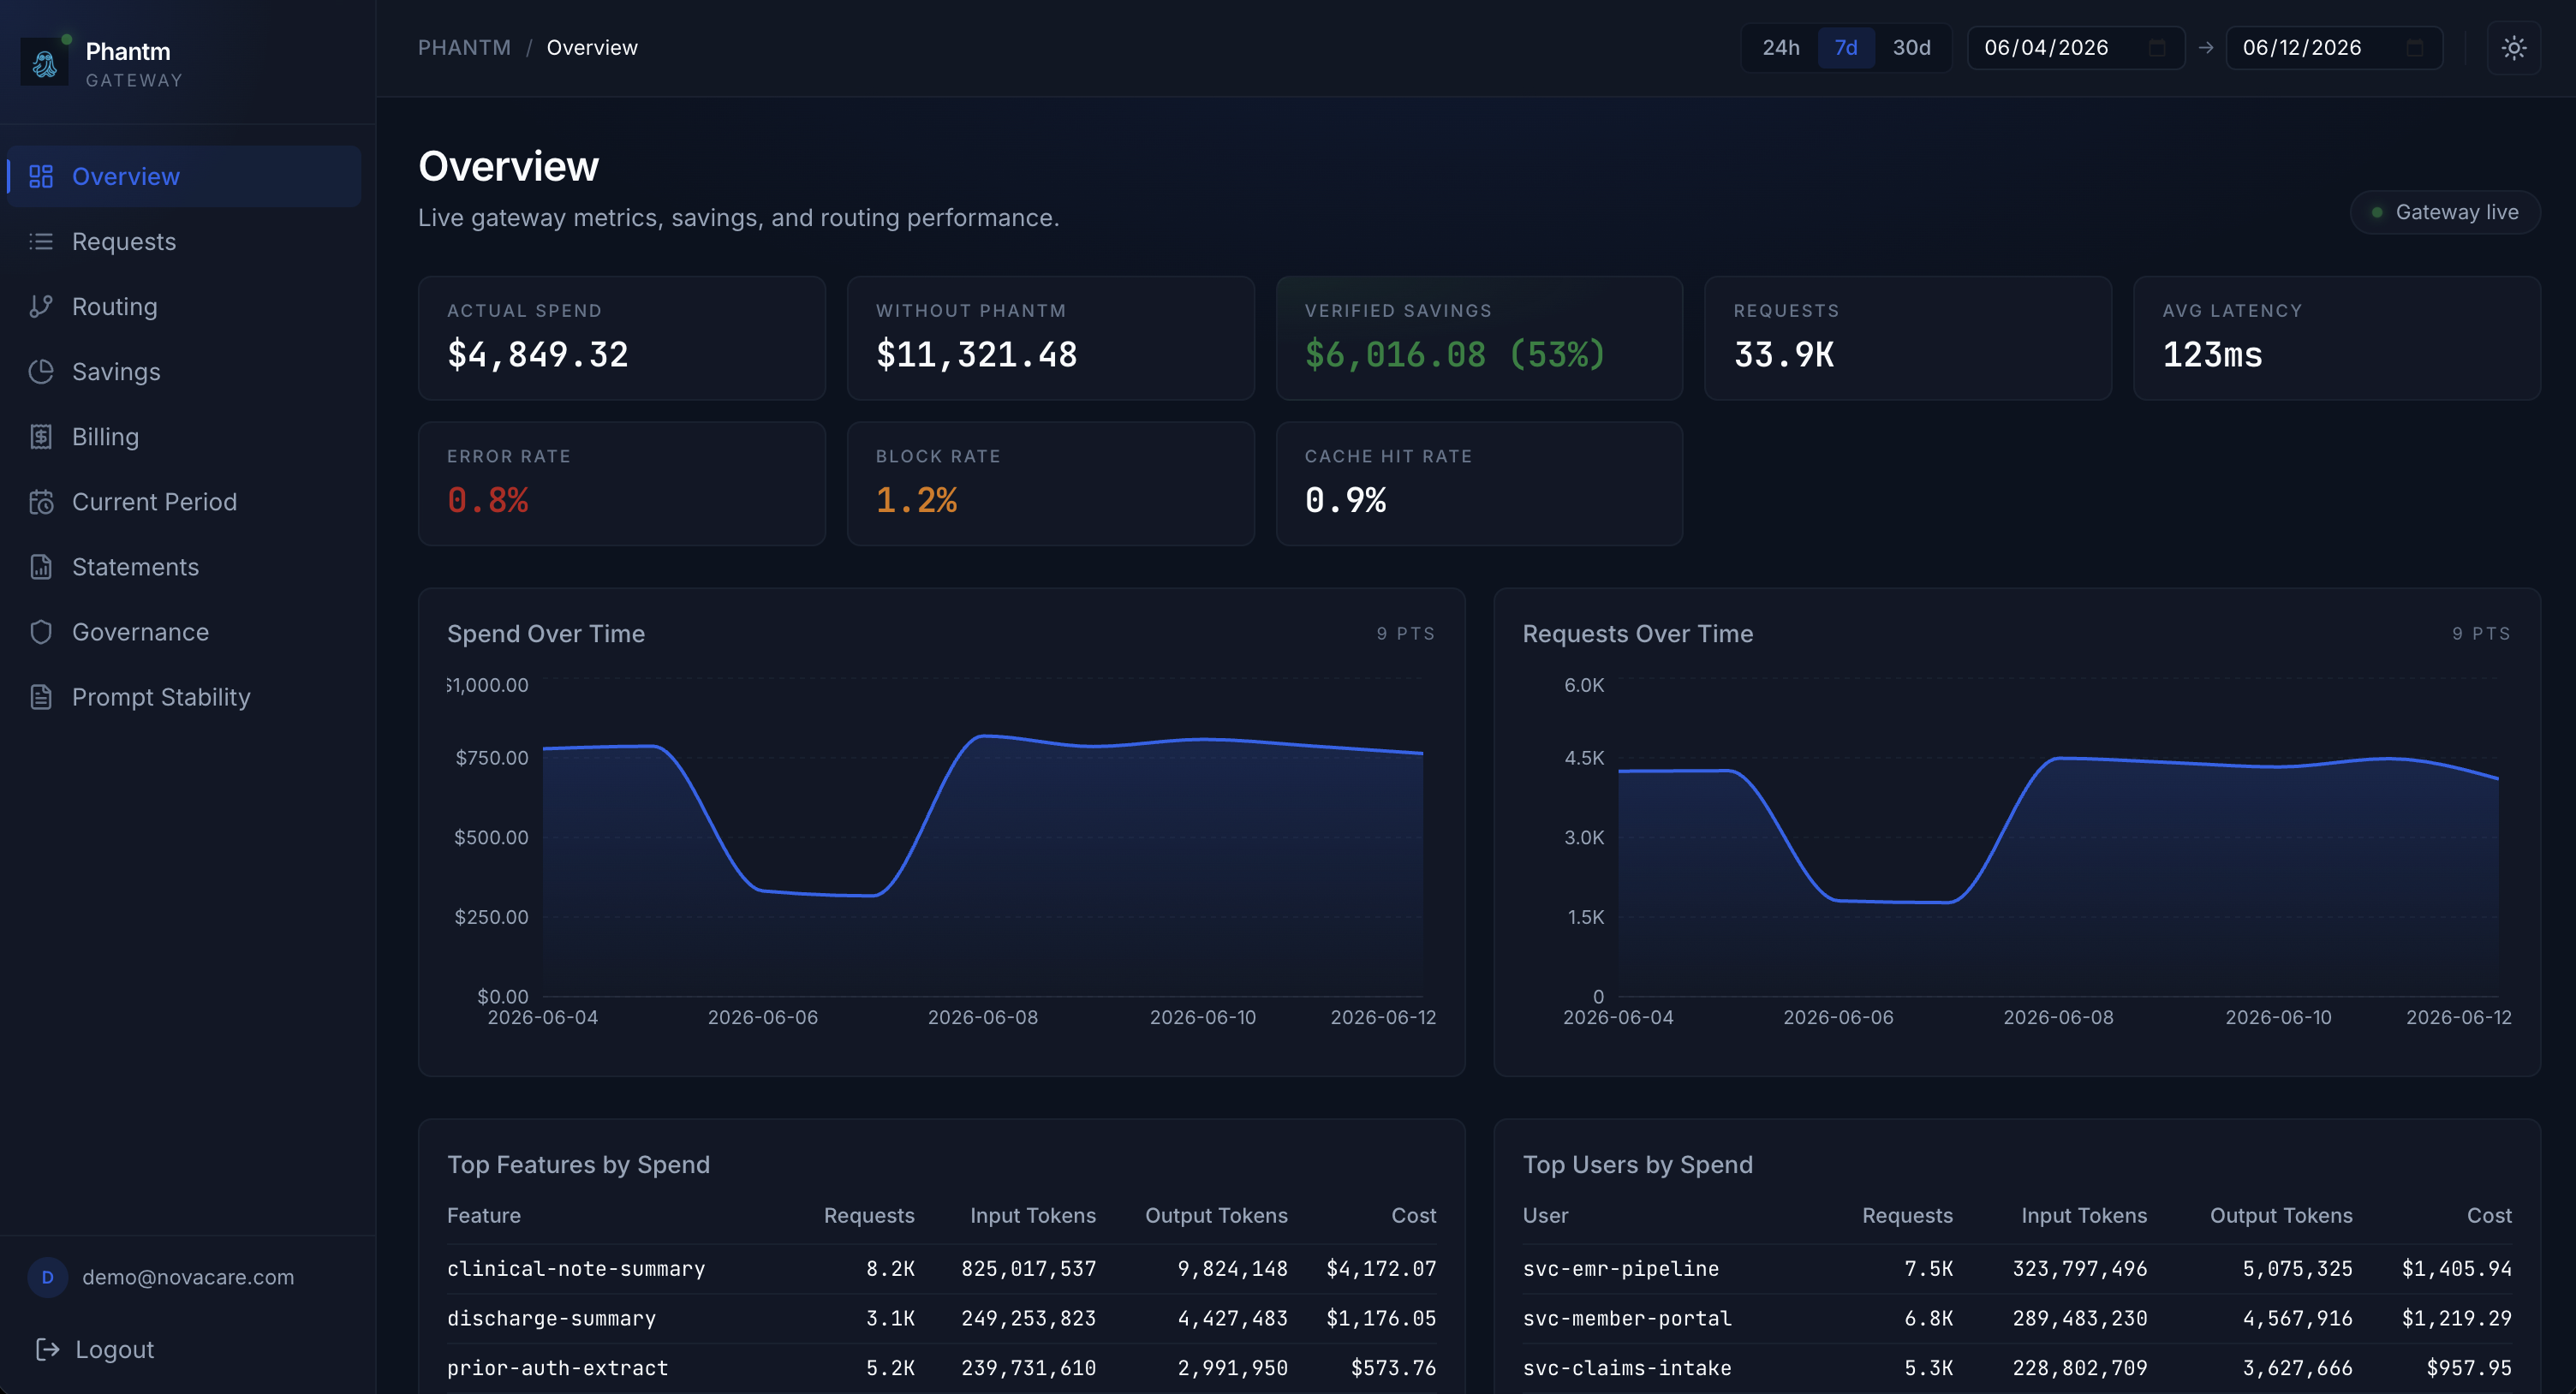
A new kind of LLM gateway. Purpose-built for production AI workloads, Phantm optimizes every request in real time.
Intelligent routing and caching
Each of your workflows is routed to the model that serves it best, keeping warm caches intact along the way.
Frontier compression
Prompts, tool output and history are distilled to what the model needs. Fewer tokens in, the same answer out.
Learns from your traffic
Routing and compression keep improving, measured against your own evals.
Inside
one request
Phantm sits between your app and its models. Each call is trimmed, cached and routed before it leaves.
Read the docs01Trim
Oversized tool output and stale turns are removed.
02Compress
What remains is condensed without changing its meaning.
03Cache
The prompt is ordered so the provider cache hits on repeats.
04Route
The request goes to the model that serves this workflow best.
05Learn
Every result sharpens the next decision.
Benchmarked on real traffic.
We ran 15 benchmarks, public test sets plus customer-support workloads, twice: once straight to the model, once through Phantm. Same prompts, same models.
Then we compared the bills and judged every answer. Response quality stayed indistinguishable from baseline, and every optimization traces back to a diff and a reason code.
Read the full evaluation15 benchmarks · WildChat, LongBench, Hermes FC and DialogSum among them, plus production support workloads across 21 system prompts · May 2026
Let's talk.
Questions, pricing, or a benchmark on your own traffic. We reply within a day.
support@getphantm.ai